The Production AI Inference Conundrum
Senior engineers, technical founders, and CTOs building AI-powered SaaS applications often find themselves in a challenging bind. The promise of AI is immense, but the path to a high-performance, cost-effective, and scalable production system is fraught with edge cases. You've likely moved beyond simple API calls to Claude, Cursor, or Lovable in development, only to hit a wall when scaling to hundreds or thousands of active tenants.
The core problem is balancing the inherent trade-offs: delivering low-latency responses, managing unpredictable and often high inference costs, and ensuring fair, isolated usage across a multi-tenant user base. Generic solutions quickly buckle under variable load, leading to spiraling cloud bills, inconsistent user experiences, and a constant firefighting effort. This isn't about just making an API call; it's about building a resilient, intelligent inference layer.
TL;DR
- Traditional AI inference setups struggle with multi-tenancy, variable load, and cost unpredictability.
- An ASTRA-like architecture optimizes for cost, latency, and scalability through intelligent design.
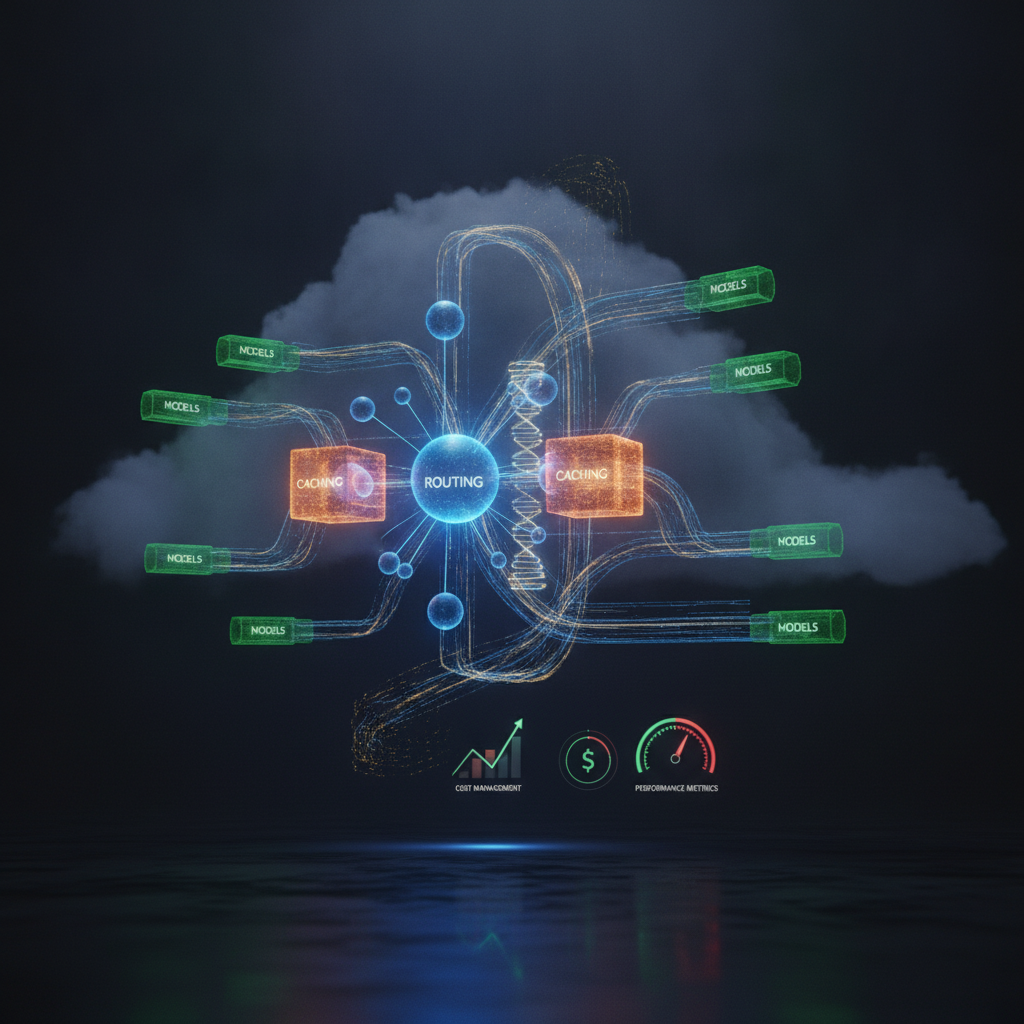
- Key components include dynamic routing, batching, caching, and tiered model usage.
- Robust production systems demand idempotency, comprehensive error handling, and real-time cost tracking.
- Leverage specialist engineering to navigate complex production AI challenges without trial-and-error.
Introducing ASTRA-like Architectures for AI SaaS
To address these challenges, we advocate for an 'ASTRA-like' architectural approach. ASTRA, in this context, stands for Adaptive, Scalable, Transparent, Resilient, and Automated inference. It's a conceptual framework designed to move beyond basic API proxying to a sophisticated system that dynamically manages AI inference requests.
The goal is to provide a consistent, high-quality AI experience for every tenant while keeping operational costs predictable and manageable. This involves a shift from treating AI models as black boxes to actively orchestrating their usage based on real-time demand, tenant profiles, and cost considerations.
Core Principles of ASTRA-like Systems
An ASTRA-like system is built on several foundational principles:
- Dynamic Resource Allocation: Provisioning or scaling inference resources (e.g., GPU instances, serverless functions) up or down based on actual demand, not peak capacity.
- Intelligent Request Routing: Directing each inference request to the most appropriate model and endpoint based on factors like cost, latency, model capability, and tenant-specific configurations.
- Cost-Aware Processing: Integrating real-time cost tracking and optimization into every inference decision, potentially even influencing model choice or processing strategy.
- Resilience and Fault Tolerance: Designing for failures, including transient API errors, rate limits, and model performance degradation, with robust retry mechanisms and fallback options.
- Transparency and Observability: Providing clear insights into inference performance, costs, and potential issues through comprehensive logging, metrics, and tracing.
Key Pillars of an Optimized AI Inference System
Building out an ASTRA-like architecture requires careful consideration of several interconnected components.
Intelligent Request Routing and Load Balancing
Not all inference requests are created equal. A simple chatbot query might be served by a smaller, cheaper model, while a complex document summarization requires a more powerful, expensive one. An intelligent router can inspect incoming requests (based on prompt length, complexity, tenant tier, or specific feature flags) and direct them to the optimal inference endpoint.
This could mean routing to different model providers (e.g., OpenAI, Anthropic, custom fine-tuned models), different model versions, or even different tiers of the same model (e.g., gpt-3.5-turbo for quick responses, gpt-4o for accuracy). This dynamic routing is crucial for cost control and performance.
Dynamic Batching and Micro-Batching
Many AI models, especially those running on dedicated hardware, achieve better throughput and lower per-token cost when processing requests in batches. Implementing a micro-batching layer allows your system to collect multiple concurrent requests and send them to the AI model in a single, larger inference call. This reduces the fixed overhead per request, making more efficient use of resources.
However, batching introduces latency. A well-designed system balances batch size with acceptable latency, potentially using dynamic batching where the batch size adapts based on current load and desired response times.
Caching Inference Results
For deterministic or frequently asked queries, caching inference results can drastically reduce costs and latency. If a user asks the same question, or a common internal process triggers the same AI prompt, serving a cached response is far cheaper and faster than re-running the inference. Implement a robust caching strategy with appropriate invalidation policies, especially for dynamic or personalized content.
Model Tiering and Specialization
Beyond routing, consider a tiered model strategy. For example, a basic tier might use a highly optimized, smaller model for common requests, while a premium tier offers access to larger, more capable (and more expensive) models. This aligns cost with value for different tenant segments and allows for granular control over resource allocation.
Asynchronous Processing and Queues
Long-running inference tasks (e.g., generating detailed reports, processing large documents) should be handled asynchronously. Integrating a message queue (like AWS SQS, RabbitMQ, or Kafka) allows your frontend or API to quickly acknowledge a request, queue it for processing, and then notify the user or callback an endpoint once the inference is complete. This prevents timeouts, improves user experience, and decouples the inference service from the request-response cycle.
Cost Tracking and Billing Integration
One of the most critical aspects of production AI SaaS is accurate, real-time cost tracking. Each inference request should be tagged with tenant identifiers, model used, token counts, and estimated cost. This data feeds into your usage-based billing system, ensuring you can accurately charge tenants for their consumption and monitor your own expenditures.
This is where a robust system for tracking AI credits and usage becomes indispensable. You can read more about building such a system in our article on AI Credits System for SaaS with Stripe.
Implementing Robustness: Beyond the Happy Path
Production systems are defined by how they handle failures, not just successes.
Idempotency for Inference Requests
Network issues, client retries, or webhook duplication can lead to the same inference request being sent multiple times. Without idempotency, this results in duplicate processing, wasted costs, and potentially incorrect data. Implement an idempotency key (e.g., a UUID) with every request. Your inference service should store this key and the result, returning the stored result if the same key is received again within a defined window.
Error Handling and Retries
AI APIs can be flaky. Rate limits, transient network errors, or internal service issues are common. Your inference layer must implement intelligent retry logic with exponential backoff. Distinguish between retryable errors (e.g., 429 Too Many Requests, 5xx server errors) and non-retryable errors (e.g., 400 Bad Request due to invalid prompt). For non-retryable errors, fail fast and provide clear error messages.
Security and Data Isolation
In a multi-tenant environment, tenant data privacy is paramount. Ensure that inference requests are properly authenticated and authorized. If you're sharing inference resources, implement strict data isolation to prevent cross-tenant data leakage. This might involve using separate model instances, secure data pipelines, or careful access control policies.
Observability
Comprehensive logging, metrics, and distributed tracing are non-negotiable. You need to know: which tenant made which request, which model was used, how long it took, how many tokens were consumed, and if any errors occurred. This data is vital for debugging, performance optimization, and cost analysis. Integrate with tools like Datadog, New Relic, or Prometheus/Grafana.
Code Example: A Next.js API Route for Intelligent AI Inference Proxy
This Next.js App Router example demonstrates a simplified proxy for OpenAI inference, incorporating idempotency, basic routing, and retry logic. In a real-world scenario, the idempotency store would be a persistent database (like Redis or PostgreSQL) and the routing logic far more complex.
// app/api/inference/route.ts
import { NextResponse } from 'next/server';
import OpenAI from 'openai';
import { v4 as uuidv4 } from 'uuid';

// In a real app, this would be retrieved securely and dynamically
const OPENAI_API_KEY = process.env.OPENAI_API_KEY;
const openai = new OpenAI({ apiKey: OPENAI_API_KEY });

// A simple in-memory store for idempotency keys. NOT FOR PRODUCTION.
// In production, use Redis, a database table, or a dedicated idempotency service.
const processedRequests = new Map<string, { result: any; status: number; timestamp: number }>();
const IDEMPOTENCY_EXPIRY_MS = 3600 * 1000; // 1 hour for example

export async function POST(request: Request) {
  const { prompt, model, tenantId, idempotencyKey: clientProvidedIdempotencyKey } = await request.json();

  if (!prompt || !model || !tenantId) {
    return NextResponse.json({ error: 'Missing required fields: prompt, model, tenantId' }, { status: 400 });
  }

  // Generate or use client-provided idempotency key
  const idempotencyKey = clientProvidedIdempotencyKey || uuidv4();

  // Check for idempotency
  const existingRequest = processedRequests.get(idempotencyKey);
  if (existingRequest && (Date.now() - existingRequest.timestamp < IDEMPOTENCY_EXPIRY_MS)) {
    console.warn(`Idempotent request detected for key: ${idempotencyKey}. Returning cached result.`);
    return NextResponse.json(existingRequest.result, { status: existingRequest.status });
  }

  let retries = 3;
  const baseDelay = 100; // ms

  while (retries > 0) {
    try {
      // Simulate intelligent routing/model selection based on tenantId or prompt complexity
      // In a real system, this could involve a lookup service, A/B testing, or feature flags.
      const effectiveModel = model === 'fast' ? 'gpt-3.5-turbo' : 'gpt-4o'; // Simplified logic

      // Simulate cost tracking (this would be more sophisticated in production)
      // Example costs, refer to actual OpenAI pricing for accurate figures.
      const estimatedCostPerToken = effectiveModel === 'gpt-3.5-turbo' ? 0.0000015 : 0.000015; // Example
      console.log(`Processing with ${effectiveModel} for tenant ${tenantId}. Estimated cost: ${estimatedCostPerToken} per token.`);

      const chatCompletion = await openai.chat.completions.create({
        model: effectiveModel,
        messages: [{ role: 'user', content: prompt }],
        temperature: 0.7,
        max_tokens: 150,
        // Add custom headers for tracing/logging if your AI provider supports it
        extra_headers: { 'X-Request-ID': idempotencyKey, 'X-Tenant-ID': tenantId },
      });

      const result = chatCompletion.choices[0].message.content;
      const usage = chatCompletion.usage; // Contains prompt_tokens, completion_tokens

      // Log cost for billing system or trigger an update
      const actualCost = ((usage?.prompt_tokens || 0) * estimatedCostPerToken) + ((usage?.completion_tokens || 0) * estimatedCostPerToken);
      console.log(`Actual cost for tenant ${tenantId} with key ${idempotencyKey}: $${actualCost.toFixed(6)}`);
      // In a production system, this would trigger an event to your billing service.

      const responseBody = { result, usage, idempotencyKey, actualCost };
      processedRequests.set(idempotencyKey, { result: responseBody, status: 200, timestamp: Date.now() });
      return NextResponse.json(responseBody, { status: 200 });

    } catch (error: any) {
      console.error(`AI inference failed (retry ${retries}):`, error.message);

      // Specific error handling for rate limits, transient errors
      if (error.status === 429 || error.code === 'rate_limit_exceeded') {
        const retryAfter = error.headers?.get('retry-after') || Math.pow(2, 3 - retries) * baseDelay / 1000; // Default to exponential backoff
        console.warn(`Rate limit hit. Retrying after ${retryAfter} seconds.`);
        await new Promise(resolve => setTimeout(resolve, retryAfter * 1000));
      } else if (error.code === 'context_length_exceeded') {
        // Non-retryable user error
        processedRequests.set(idempotencyKey, { result: { error: 'Prompt too long for the selected model.' }, status: 400, timestamp: Date.now() });
        return NextResponse.json({ error: 'Prompt too long for the selected model.' }, { status: 400 });
      } else if (error.status && error.status >= 500) {
        // General server errors from upstream API are usually retryable
        await new Promise(resolve => setTimeout(resolve, Math.pow(2, 3 - retries) * baseDelay));
      } else {
        // Other client-side errors (e.g., 400, 401, 403) are typically not retryable
        processedRequests.set(idempotencyKey, { result: { error: `AI service error: ${error.message}` }, status: error.status || 500, timestamp: Date.now() });
        return NextResponse.json({ error: `AI service error: ${error.message}` }, { status: error.status || 500 });
      }

      retries--;
    }
  }

  // If all retries fail
  const failureResponse = { error: 'Failed to process AI inference request after multiple retries.' };
  processedRequests.set(idempotencyKey, { result: failureResponse, status: 500, timestamp: Date.now() });
  return NextResponse.json(failureResponse, { status: 500 });
}
This snippet illustrates how to build a robust API proxy. The processedRequests Map is a simple, non-production example for demonstrating idempotency; in a real system, you'd use a durable store like Redis or a database table for reliability and persistence across server restarts.
Key Takeaways
- Strategic Optimization: Don't treat AI inference as a black box. Implement intelligent routing, batching, and caching to optimize for cost and latency.
- Robustness is Paramount: Design for failure with idempotency, comprehensive error handling, and smart retry mechanisms. This prevents duplicate charges and improves reliability.
- Cost Visibility: Integrate real-time cost tracking into your inference pipeline. This is essential for accurate usage-based billing and managing your operational expenses.
- Multi-tenancy Mindset: Ensure tenant isolation, fair usage, and secure data handling are core to your architecture from day one.
- Observability: Implement thorough logging, metrics, and tracing to quickly diagnose issues and understand system performance.
Ship this without the trial-and-error
Building high-performance, cost-optimized AI inference systems for multi-tenant SaaS applications is a complex engineering challenge. It requires deep expertise in AI architectures, cloud infrastructure, and robust software engineering practices. If your team is grappling with unpredictable costs, latency issues, or scaling bottlenecks, you don't have to navigate these production edge cases alone.
PolarSoftBD specializes in Production Payments & AI Engineering, helping technical founders and CTOs architect and implement sophisticated AI SaaS solutions that scale reliably and cost-effectively. We've built and optimized these systems for real-world usage, understanding the nuances that generic agencies miss.
Explore our AI SaaS Development services to see how we can accelerate your product's journey to market. Or, for a direct conversation about your specific challenges, book a free strategy call with PolarSoftBD.