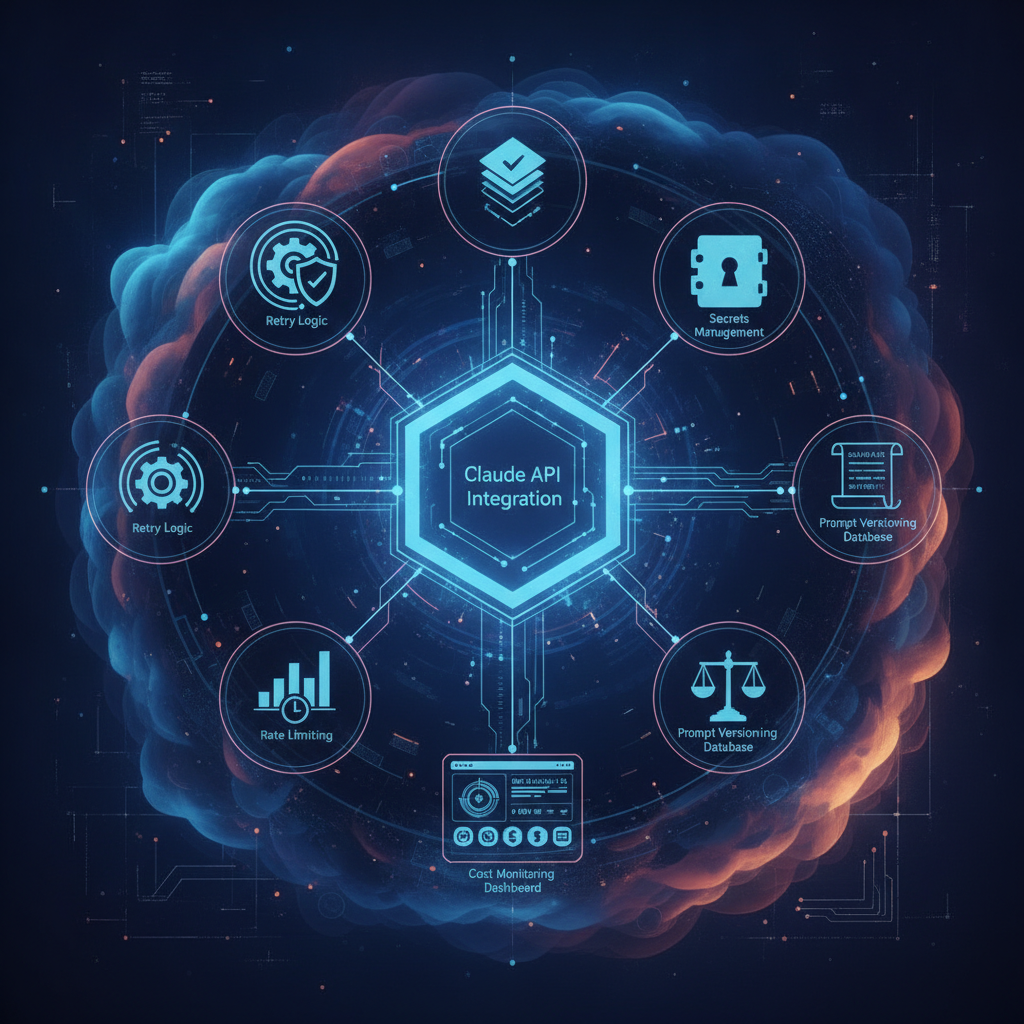
You've experimented with Claude, perhaps built a compelling prototype that showcases its impressive reasoning capabilities. But when it comes to integrating large language models (LLMs) like Claude into a production AI SaaS application, the journey from proof-of-concept to a reliable, cost-effective, and secure system is fraught with edge cases. Technical founders and CTOs building AI-powered SaaS often find themselves grappling with issues far beyond basic API calls: managing transient failures, optimizing token usage, securing sensitive data in prompts, and ensuring consistent model behavior across deployments.
This article is for engineers who have already tried basic integrations and are now facing the realities of production. We'll explore the architectural patterns and practical strategies PolarSoftBD employs to build robust Claude integrations that stand up to real-world demands.
TL;DR
- Implement a resilient Claude API wrapper with exponential backoff, retries, and circuit breaker patterns to handle transient failures and rate limits.
- Externalize and version your prompts to enable iterative improvements, A/B testing, and seamless rollbacks without code deployments.
- Prioritize cost optimization by monitoring token usage, strategically selecting Claude models (Opus, Sonnet, Haiku), and implementing intelligent caching.
- Fortify your integration's security by protecting sensitive data in prompts, validating model outputs, and mitigating prompt injection risks.
- Beyond the API call, consider the full lifecycle: error handling, observability, and the impact of LLM behavior on downstream systems.
The Gap Between Prototype and Production
Starting with anthropic.messages.create is straightforward. You send a prompt, you get a response. This simplicity is deceptive. In a production environment, your application will face network latency, API rate limits, unexpected model behaviors, and the constant need to iterate on prompts. A direct, unadorned API call quickly becomes a bottleneck and a source of instability.
Production-grade systems require a layer of abstraction that handles these complexities gracefully. This layer, often an API wrapper or service, is responsible for ensuring reliability, managing cost, maintaining security, and providing observability. Without it, your AI SaaS will struggle with uptime, unpredictable expenses, and difficult debugging cycles, ultimately eroding user trust and increasing operational overhead.
Building a Resilient Claude API Wrapper
The foundation of any robust LLM integration is a well-designed API wrapper. This isn't just about calling the anthropic client; it's about embedding resilience directly into your interaction layer.
Handling Transient Failures and Rate Limits
LLM APIs, like any external service, can experience transient network issues, temporary server overloads, or rate limiting. A naive approach would simply throw an error, interrupting the user experience or failing a critical background job. A production system must implement intelligent retry mechanisms.
Exponential backoff with jitter is the standard. When a retryable error (e.g., HTTP 429 Too Many Requests, or 5xx server errors) occurs, the system waits for an increasingly longer period before retrying. Jitter (adding a small random delay) helps prevent a thundering herd problem where many retries from different clients hit the API simultaneously after a shared delay.
Consider adding a circuit breaker pattern. If an API endpoint consistently fails over a period, the circuit breaker can temporarily 'trip', preventing further calls to that endpoint for a defined duration. This prevents your application from hammering a failing service and allows the upstream service to recover, while also failing fast on your end for new requests.
// src/lib/claude-wrapper.ts
import Anthropic from "@anthropic-ai/sdk";
import { AnthropicError } from "@anthropic-ai/sdk";

interface ClaudeConfig {
  apiKey: string;
  maxRetries?: number;
  initialDelayMs?: number;
  logFn?: (message: string, ...args: any[]) => void;
}

interface ClaudeMessageParams extends Anthropic.Messages.MessageCreateParams {
  userId?: string;
  featureName?: string;
}

class ProductionClaudeClient {
  private client: Anthropic;
  private maxRetries: number;
  private initialDelayMs: number;
  private log: (message: string, ...args: any[]) => void;

  constructor(config: ClaudeConfig) {
    if (!config.apiKey) {
      throw new Error("Anthropic API Key is required.");
    }
    this.client = new Anthropic({ apiKey: config.apiKey });
    this.maxRetries = config.maxRetries ?? 3;
    this.initialDelayMs = config.initialDelayMs ?? 1000;
    this.log = config.logFn ?? console.log;
  }

  /**
   * Makes a robust call to the Claude Messages API with retry logic and error handling.
   * @param params Message creation parameters.
   * @param attempt Current retry attempt (internal).
   * @returns The Claude API response.
   */
  async createMessage(params: ClaudeMessageParams, attempt = 0): Promise<Anthropic.Messages.Message> {
    try {
      this.log(`Claude API call for user ${params.userId || 'N/A'}, feature ${params.featureName || 'N/A'}. Attempt ${attempt + 1}.`);

      // Optionally, add pre-flight checks or cost estimation here
      // e.g., estimate token count for the prompt

      const response = await this.client.messages.create(params);

      // Log token usage for cost tracking
      this.log(`Claude API call successful. Input tokens: ${response.usage.input_tokens}, Output tokens: ${response.usage.output_tokens}`);

      return response;
    } catch (error) {
      if (error instanceof AnthropicError) {
        this.log(`Claude API Error (attempt ${attempt + 1}): ${error.status} - ${error.message}`);

        // Retryable errors: 429 (Rate Limit), 5xx (Server Errors)
        if (
          (error.status === 429 || (error.status && error.status >= 500 && error.status < 600)) &&
          attempt < this.maxRetries
        ) {
          const delay = this.initialDelayMs * Math.pow(2, attempt) + Math.random() * 100; // Exponential backoff with jitter
          this.log(`Retrying Claude API call in ${delay}ms...`);
          await new Promise(resolve => setTimeout(resolve, delay));
          return this.createMessage(params, attempt + 1);
        }
      } else {
        this.log(`Unexpected error during Claude API call: ${error}`);
      }

      // Re-throw if not retryable or max retries reached
      throw error;
    }
  }

  // Example of a structured output call, useful for function calling or strict JSON responses
  async createStructuredMessage<T>(
    params: Omit<ClaudeMessageParams, 'tools' | 'tool_choice'>,
    toolSchema: { name: string; description: string; input_schema: any },
    attempt = 0
  ): Promise<T> {
    const toolCallParams: Anthropic.Messages.MessageCreateParams = {
      ...params,
      tools: [toolSchema],
      tool_choice: { type: 'tool', name: toolSchema.name },
    };

    const response = await this.createMessage(toolCallParams, attempt);

    const toolUse = response.content.find(
      (block): block is Anthropic.Messages.ToolUseBlock => block.type === 'tool_use'
    );

    if (!toolUse || toolUse.name !== toolSchema.name) {
      throw new Error('Claude did not return the expected tool call.');
    }

    return toolUse.input as T;
  }
}
Managing API Keys and Credentials Securely
Your Claude API key is a sensitive credential. It should never be hardcoded or exposed client-side. Utilize environment variables (e.g., .env.local for Next.js) and securely manage them in your deployment environment (e.g., Vercel's environment variables, AWS Secrets Manager, Google Secret Manager). Ensure that your backend services access these keys with the principle of least privilege.
Advanced Prompt Engineering and Lifecycle Management
Prompts are the lifeblood of your AI application. They are not static; they evolve. Managing this evolution effectively is crucial for maintaining model performance and enabling rapid iteration.
Versioning Prompts for Iteration and Rollback
Hardcoding prompts directly into your application code is a common anti-pattern for production systems. It couples your application logic tightly with your prompt strategy, making updates cumbersome and rollbacks difficult. Instead, externalize your prompts.
Store prompts in a centralized, version-controlled system. This could be a database table, a dedicated configuration service, or even simple JSON files managed in your Git repository. Each prompt should have a unique identifier and a version number. This approach allows you to:
- Iterate rapidly: Experiment with new prompts without deploying new code.
- A/B test: Serve different prompt versions to different user segments to evaluate performance.
- Rollback easily: Revert to a previous prompt version if a new one introduces regressions.
- Audit changes: Track who changed what prompt and when.
Guardrails for Model Output
Claude is powerful, but its output isn't always perfectly structured or safe for direct consumption. Implement guardrails to ensure reliability and security.
- Structured Output: For tasks requiring specific data formats (e.g., JSON), leverage Claude's tool use capabilities or instruct it explicitly to return JSON. Always parse and validate the JSON output to ensure it conforms to your expected schema.
- Post-processing and Validation: After receiving a response, apply additional validation logic. Check for expected keywords, length constraints, or data types. If the output is critical for a downstream process, consider human-in-the-loop validation for edge cases.
- Content Moderation: Depending on your application's domain, you might need to implement your own content moderation layer on top of Claude's inherent safety features. This could involve checking for PII, hate speech, or other undesirable content before displaying it to users or storing it.
Cost Optimization Strategies
LLM usage can quickly become a significant operational cost. Proactive cost management is essential for a sustainable AI SaaS business model, especially when you're building usage-based billing systems.
Token Usage Monitoring and Alerts
Every interaction with Claude consumes tokens. It's critical to monitor this usage closely. Integrate logging within your API wrapper (as shown in the code snippet) to capture input and output token counts for each request. Store this data in your observability platform or database, linking it to specific users, features, or tenants.
Set up alerts for unusual spikes in token usage or when daily/monthly budgets are approaching their limits. This allows you to react quickly to inefficient prompts, unexpected usage patterns, or potential abuse.
Strategic Model Selection
Claude offers a range of models, each with different capabilities and price points:
- Opus: The most intelligent and expensive model, ideal for complex reasoning, multi-step tasks, and high-stakes applications.
- Sonnet: A balanced model offering strong performance at a lower cost, suitable for a wide range of enterprise workloads.
- Haiku: The fastest and most cost-effective model, perfect for quick, simple tasks where speed and low latency are paramount.
Do not default to Opus for every task. Analyze the requirements of each feature in your application and select the least expensive model that still meets your performance and quality criteria. For example, a simple summarization task might be perfectly handled by Haiku, while complex code generation requires Opus.
Consider implementing a caching layer for frequently requested or deterministic prompts. If a user asks the same question or triggers the same prompt with identical parameters, serving a cached response can significantly reduce API calls and costs. However, be mindful of data freshness and user expectations when caching LLM outputs.
Security Considerations for LLM Integrations
Security in AI applications is paramount, especially when handling user data or sensitive information. LLM integrations introduce new attack vectors that require careful attention.
Protecting Sensitive Data in Prompts and Responses
Users will inevitably input sensitive data into your AI application. You must have a clear strategy for handling this information:
- PII Redaction/Anonymization: Implement pre-processing steps to identify and redact or anonymize Personally Identifiable Information (PII) from user prompts before sending them to Claude. Similarly, scan Claude's responses for PII before displaying them or storing them in your database.
- Data Residency: Understand where Claude processes data. If your application has strict data residency requirements (e.g., GDPR, HIPAA), ensure your chosen LLM provider and configuration comply.
- Least Privilege: Limit the scope of data sent to Claude. Only include the information absolutely necessary for the model to perform its task.
Mitigating Prompt Injection Risks
Prompt injection is a significant threat where malicious users craft prompts to override the system's instructions or extract confidential information. While Claude has built-in safety features, a multi-layered defense is crucial.
- Input Sanitization: While LLMs are designed to understand natural language, sanitizing user inputs for common injection patterns (e.g., SQL injection, XSS) is still a good practice, especially if the LLM's output is used in other systems.
- Output Validation: Never trust LLM output implicitly. If Claude generates code, commands, or structured data, validate it rigorously before execution or use. For instance, if Claude suggests a database query, ensure it adheres to a safe schema and doesn't contain destructive operations.
- Separation of Concerns: Design your application so that the LLM's role is clearly defined and limited. Avoid giving the LLM direct control over critical system functions without human or automated oversight.
Key Takeaways
Building production-grade applications with Claude is a journey that extends far beyond the initial API call. It demands a thoughtful approach to reliability, cost, security, and maintainability. By investing in a robust API wrapper, implementing intelligent prompt management, optimizing for cost, and prioritizing security, you can transform your AI prototype into a resilient, scalable, and trustworthy AI SaaS product.
Remember, the goal is not just to make Claude work, but to make it work reliably, efficiently, and securely for your users, day in and day out. This focus on engineering excellence is what differentiates a successful AI product in the market.
Ship this without the trial-and-error
Navigating the complexities of production AI engineering, especially with sophisticated models like Claude, can consume valuable development cycles. At PolarSoftBD, we specialize in architecting and building robust AI SaaS platforms, including complex Claude integrations, multi-tenant architectures, and AI credits systems. Don't let production edge cases slow your time to market or compromise your product's reliability.
Explore our expertise in AI SaaS Development or learn more about building a scalable AI Credits System for your SaaS.
Ready to build your AI product with confidence? Schedule a free strategy call with PolarSoftBD to discuss your project.