- usage tracking
- AI analytics
- idempotency
- real-time data
- high-traffic systems
- Next.js
Real-time Usage Tracking for AI Analytics: Engineering Idempotent Systems at Cricbuzz Scale
Developers and CTOs building high-traffic, AI-powered platforms often struggle with accurately tracking granular user engagement for premium features.
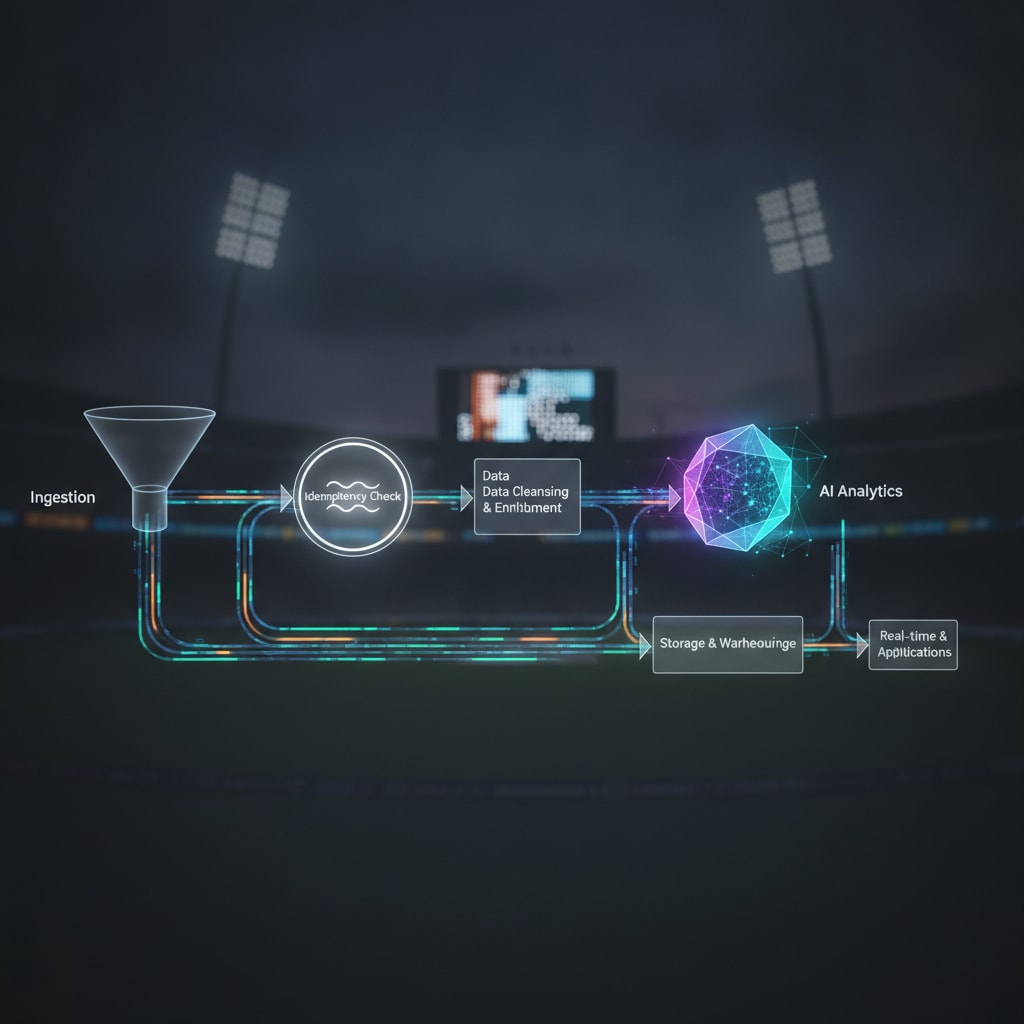
You’re building an AI-powered platform, perhaps offering advanced analytics, personalized content generation, or predictive insights. Your users are interacting with these features at a high velocity, and you need to accurately track every single interaction – every AI query, every generated report, every unique view of a premium insight. This isn't just about vanity metrics; it's about the foundation for your monetization strategy, whether that's a credit system, usage-based tiers, or internal resource allocation.
Imagine a platform like Cricbuzz, a global leader in cricket news and scores, deciding to roll out premium AI-driven match predictions or personalized player performance analytics. How do they reliably count each access to these valuable features without missing a beat, even under immense traffic? How do they ensure that a user querying an AI model twice due to a network glitch isn't charged for two queries? This is the core problem: building a robust, real-time, and crucially, idempotent usage tracking system for high-traffic AI analytics.
This challenge isn't unique to sports platforms. Technical founders, CTOs, and senior engineers across AI SaaS and data-intensive applications face this exact hurdle. You've likely tried basic logging or simple database inserts, only to hit production edge cases like duplicate events, race conditions, or performance bottlenecks under load. You need a system that guarantees accuracy and resilience, mirroring the reliability demands of production payment systems.
TL;DR
- Implement robust, idempotent usage event ingestion to ensure each event is counted exactly once.
- Utilize message queues for resilient, asynchronous processing, decoupling event capture from complex logic.
- Design a scalable data model in PostgreSQL (e.g., Supabase) for efficient aggregation and querying.
- Secure your tracking endpoints with authentication and rate limiting to prevent abuse.
- Prepare your tracking data for seamless downstream monetization (credit systems, usage-based billing).
The Challenge of High-Volume, Granular Usage Events
Tracking every user interaction with an AI model or a premium data point sounds straightforward until you consider the scale and inherent unreliability of distributed systems. Network retries, concurrent requests, and client-side glitches mean that a single user action can easily trigger multiple identical event submissions. Without a robust mechanism, these duplicates will corrupt your usage data, leading to incorrect billing, skewed analytics, and ultimately, frustrated users or internal stakeholders.
The parallels to production payment systems are striking. Just as a charge.succeeded webhook must be processed exactly once to prevent double-charging, a ai_query.executed event must be recorded exactly once to ensure fair usage tracking. Both scenarios demand idempotency – the guarantee that an operation can be performed multiple times without changing the result beyond the initial application. This is what separates a simple logging system from a production-grade usage tracking engine.
Architecting for Idempotency: The Core Principle
Idempotency is the cornerstone of reliable usage tracking. It ensures that even if your system receives the same usage event multiple times, it only processes and counts it once. The key to achieving this is a unique identifier, often called an idempotencyKey, generated by the client or the immediate upstream service when the event is first initiated.
When a usage event hits your API, the first step is to check if an event with that specific idempotencyKey has already been recorded for the given user and event type. If it has, you simply acknowledge receipt and discard the duplicate. If not, you process the event and record the idempotencyKey alongside it.
This check must be atomic and fast. A database unique constraint on (user_id, event_type, idempotency_key) is often the most reliable way to enforce this at the persistence layer, catching any race conditions where two identical events might attempt to insert simultaneously.
// app/api/usage/route.ts
import { NextRequest, NextResponse } from 'next/server';
import { createClient } from '@supabase/supabase-js';
import { v4 as uuidv4 } from 'uuid';

// Initialize Supabase client (ensure env vars are set)
const supabaseUrl = process.env.NEXT_PUBLIC_SUPABASE_URL!;
const supabaseKey = process.env.SUPABASE_SERVICE_ROLE_KEY!; // Use service role key for backend operations
const supabase = createClient(supabaseUrl, supabaseKey);

export async function POST(req: NextRequest) {
  try {
    const {
      userId,
      eventType,
      resourceId,
      idempotencyKey, // Client-provided unique key for idempotency
      metadata = {},
    } = await req.json();

    if (!userId || !eventType || !idempotencyKey) {
      return NextResponse.json({ error: 'Missing required fields' }, { status: 400 });
    }

    // 1. Idempotency Check
    // Check if an event with this idempotencyKey has already been processed for this user/event type
    const { data: existingEvent, error: fetchError } = await supabase
      .from('usage_events')
      .select('id')
      .eq('idempotency_key', idempotencyKey)
      .eq('user_id', userId) // Scope idempotency key by user if relevant
      .eq('event_type', eventType) // Scope by event type too
      .limit(1);

    if (fetchError) {
      console.error('Supabase fetch error during idempotency check:', fetchError);
      return NextResponse.json({ error: 'Internal server error' }, { status: 500 });
    }

    if (existingEvent && existingEvent.length > 0) {
      // Event already processed, return success to the client
      console.warn(`Duplicate event received for idempotencyKey: ${idempotencyKey}`);
      return NextResponse.json({ message: 'Event already processed' }, { status: 200 });
    }

    // 2. Insert new usage event
    const { data, error: insertError } = await supabase
      .from('usage_events')
      .insert({
        id: uuidv4(), // Generate a unique ID for the event record
        user_id: userId,
        event_type: eventType,
        resource_id: resourceId,
        idempotency_key: idempotencyKey,
        metadata: metadata,
        timestamp: new Date().toISOString(),
      })
      .select(); // Return the inserted record

    if (insertError) {
      console.error('Supabase insert error:', insertError);
      // More robust error handling: retry logic, dead-letter queue integration here
      return NextResponse.json({ error: 'Failed to record usage event' }, { status: 500 });
    }

    // Optional: Publish to a message queue for async processing (e.g., aggregation, credit deduction)
    // await publishToQueue('usage_events_queue', data[0]);

    return NextResponse.json({ message: 'Usage event recorded successfully', event: data[0] }, { status: 201 });

  } catch (error) {
    console.error('Unexpected error processing usage event:', error);
    return NextResponse.json({ error: 'Internal server error' }, { status: 500 });
  }
}

// Example Supabase table schema (SQL):
/*
CREATE TABLE public.usage_events (
  id uuid PRIMARY KEY DEFAULT uuid_generate_v4(),
  user_id uuid NOT NULL,
  event_type text NOT NULL,
  resource_id text, -- e.g., ID of the AI model output, article viewed
  idempotency_key text NOT NULL,
  metadata jsonb,
  timestamp timestamptz DEFAULT now()
);

-- Add a unique constraint for idempotency
CREATE UNIQUE INDEX usage_events_idempotency_idx ON public.usage_events (user_id, event_type, idempotency_key);
*/
This Next.js API route demonstrates a basic idempotency check using Supabase. The idempotency_key is crucial, and the unique index on (user_id, event_type, idempotency_key) ensures data integrity at the database level.
Resilient Event Ingestion with Message Queues
Directly writing every usage event to your primary database can quickly become a bottleneck as traffic scales. Each database write involves overhead, and sustained high throughput can degrade performance for other critical operations. This is where message queues become indispensable.
By introducing a message queue (e.g., Kafka, RabbitMQ, or even a managed service like AWS SQS or Google Cloud Pub/Sub), you decouple the event capture process from the event processing logic. Your API endpoint's primary job becomes to validate the event, perform the idempotency check, and then enqueue the event. The actual database insertion, aggregation, or credit deduction happens asynchronously by a separate worker service consuming from the queue.
This architecture offers several benefits:
- Scalability: The API can handle bursts of traffic by quickly enqueuing messages, while workers can scale independently.
- Resilience: If a worker fails, messages remain in the queue to be processed later by another worker. Dead-letter queues can capture events that consistently fail processing, allowing for manual inspection and recovery.
- Decoupling: Different services can consume the same stream of usage events for various purposes (e.g., real-time analytics, billing, fraud detection) without impacting each other.
Data Modeling for Scalable Aggregation
The raw stream of usage events needs to be stored and then aggregated for reporting, analytics, and monetization. A well-designed database schema is critical for performance and flexibility.
For granular event storage, a relational database like PostgreSQL (especially with Supabase for its ease of use and RLS capabilities) is often a good choice. Your usage_events table should include:
id: A unique identifier for the event (e.g., UUID).user_id: The ID of the user who triggered the event.event_type: A descriptive string (e.g., 'ai_prediction_query', 'premium_article_view', 'data_export').resource_id: The ID of the specific resource interacted with (e.g., AI model ID, article ID).idempotency_key: The unique key used for idempotency.metadata: A JSONB column for flexible, unstructured data relevant to the event (e.g., query parameters, AI model version, response size).timestamp: When the event occurred.
For high-volume reads and aggregations, consider:
- Materialized Views: Pre-compute daily, hourly, or monthly aggregates (e.g., total AI queries per user) to speed up reporting queries.
- Time-series Databases: For extremely high-volume, continuous data streams, a specialized time-series database might be more efficient for raw event storage, while PostgreSQL handles aggregated views.
- Supabase RLS: If you're building a multi-tenant platform where different internal teams or partners need access to their specific usage data, Supabase Row Level Security (RLS) can enforce strict data isolation without complex application-level logic. This is crucial for maintaining data privacy and integrity in a shared environment.
Security and Abuse Prevention
Just like payment endpoints, usage tracking endpoints are targets for abuse. Malicious actors might try to inflate their usage (e.g., to exhaust free credits) or disrupt your system. Security must be baked in from the start.
- Authentication: Ensure that only authenticated and authorized users or services can submit usage events. API keys, JWTs, or session tokens should be validated on every request. For server-to-server communication (e.g., an AI service reporting its own usage), strong API key management is essential.
- Rate Limiting: Implement rate limiting on your usage submission endpoints to prevent denial-of-service attacks or excessive, unintended event generation. Vercel's
rate-limitmiddleware or cloud provider solutions can help here. - Input Validation: Strictly validate all incoming data to prevent injection attacks or malformed events that could crash your processing pipeline.
- Anomaly Detection: Monitor usage patterns. Sudden spikes in event volume from a single user or IP, or unusual
event_typedistributions, could indicate fraudulent activity. Automated alerts can help you react quickly.
Error Handling and Observability
In a distributed system, things will inevitably go wrong. Your usage tracking system needs robust error handling and observability to quickly identify and resolve issues.
- Comprehensive Logging: Log all successful and failed event submissions and processing steps. Include relevant IDs (
userId,idempotencyKey) for easy tracing. - Monitoring and Alerting: Use tools like Datadog, New Relic, or Prometheus/Grafana to monitor your API endpoint's latency, error rates, and message queue depths. Set up alerts for anomalies or prolonged failures.
- Dead-Letter Queues: As mentioned, use DLQs for messages that cannot be processed after multiple retries. This prevents data loss and allows for manual inspection and re-processing.
- Reconciliation: For critical usage data, implement reconciliation processes. Periodically compare aggregated usage counts with raw event logs to detect discrepancies. This is especially important before generating invoices or deducting credits.
Key Takeaways
- Idempotency is paramount: Design your system from the ground up to ensure every usage event is processed exactly once, using unique
idempotencyKeys and database constraints. - Asynchronous processing is vital for scale: Leverage message queues to decouple event capture from complex processing, improving resilience and throughput.
- Thoughtful data modeling enables efficient aggregation: Structure your raw event data for easy querying and use materialized views or specialized databases for performance.
- Security and observability are non-negotiable: Authenticate requests, rate-limit endpoints, and implement comprehensive logging and monitoring to safeguard your data and system.
- Production-grade systems demand attention to edge cases: Consider webhook retries, race conditions, and error paths as fundamental design challenges, not afterthoughts.
Ship this without the trial-and-error
Building a robust, scalable, and idempotent usage tracking system for AI analytics is a complex engineering challenge, fraught with production edge cases that can derail your product launch or lead to costly data discrepancies. At PolarSoftBD, we specialize in architecting and implementing these exact systems for high-growth AI SaaS and data platforms.
Stop wrestling with webhook duplication, race conditions, or scaling bottlenecks. Let our team of production payments and AI engineers build the resilient foundation your platform needs.
Explore our specialist AI SaaS development services: https://polarsoftbd.com/services/saas-development
Ready to discuss your specific challenges? Book a free strategy call with our engineering team: https://cal.com/shakil-khan-ul8awt/meeting-with-polarsoftbd
Further Reading:
- Need to integrate a credit system with your usage tracking? Read: https://polarsoftbd.com/blog/ai-credits-system-saas-stripe
- Building a multi-tenant platform? Learn about our approach to data isolation: https://polarsoftbd.com/blog/multi-tenant-saas-supabase-rls-architecture
Last updated October 24, 2026
Get thoughtful updates
Join our monthly digest for founders and builders.